
AI LLM
01نظرة عامة على المشروع
02التحديات والصعوبات
The product worked in a demo and struggled in production. The model was capable in general and mediocre at the one job it had. The gaps were clear:
- A general model produced generic answers, missing the industry's own terms, codes, and conventions.
- Sensitive records couldn't leave the client's environment, ruling out some hosted options entirely.
- Costs climbed with usage and were hard to predict month to month.
- Prompt changes shipped on gut feel — no way to prove a change was an improvement.
- Output format varied between calls, so downstream code broke on edge cases.
- Responses were too slow to sit inside an interactive product feature.
The opportunity was to stop treating the model as a black box and start engineering it like any other component.
03Our Approach
We measured first and changed second — the reverse of how most LLM work begins:
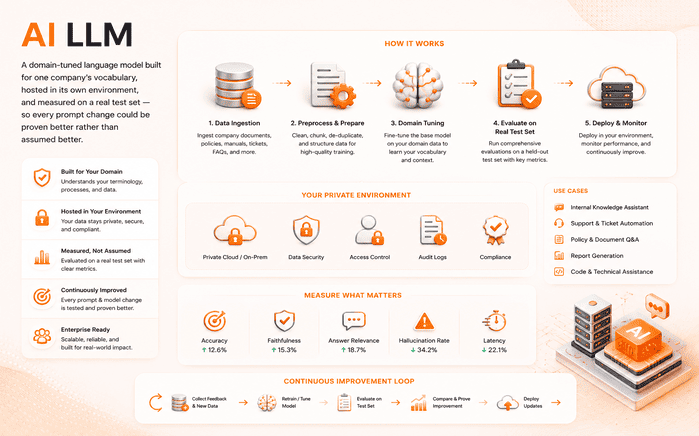
- Built an evaluation set from real production examples with agreed correct answers, before touching anything.
- Benchmarked several base models against that set rather than assuming the biggest would win.
- Fine-tuned a smaller open model on curated domain data for the narrow, high-volume tasks.
- Added routing: the tuned model handles the routine, a frontier model takes the hard cases.
- Deployed the tuned model inside the client's environment so sensitive data never leaves.
- Enforced structured output with schema validation and automatic retries on malformed responses.
- Put cost, latency, and quality on a dashboard and watched them after every release.
04What We Built
Domain Fine-Tuning
A smaller model trained on curated in-house examples until it spoke the business's language.
Evaluation Harness
A repeatable test suite that scores every model and prompt change against known-good answers.
Model Routing
Simple requests go to the cheap fast model; complex ones escalate to a stronger one automatically.
Private Deployment
The tuned model runs in the client's own cloud, keeping regulated data inside the perimeter.
Structured Output
Responses validated against a schema before release, so downstream systems get clean data.
Cost & Latency Monitoring
Spend, response time, and failure rates tracked per feature and per model, in one place.
05كيفية الاستخدام
Every request passes through a router that picks the cheapest model capable of the job. Output is validated before it leaves, and the evaluation harness gates anything heading for production.
REQUEST             MODEL LAYER                    OUTPUT
 ┌──────────────┐   ┌────────────────────────────┐   ┌──────────────────┐
 │ Product API  │   │  ROUTER  classify difficulty│   │ Schema validated │
 │ Internal app │──▶│    ├──▶ tuned small model   │──▶│ Retry if invalid │
 │ Batch job    │   │    └──▶ frontier model      │   │ Logged + costed  │
 └──────────────┘   └─────────────┬──────────────┘   └──────────────────┘
                                  │
                    ┌─────────────┴──────────────┐
                    │ EVALUATION HARNESS         │
                    │ accuracy · format · cost   │ ──▶ gates every release
                    │ latency · refusal rate     │
                    └────────────────────────────┘

Sensitive workloads never leave the client's own environment.06Problems Solved
Generic answers in a specialist domain
The general model misread industry abbreviations and product codes, producing answers that sounded fluent but were wrong in ways only an expert would catch.
Fine-tuning on curated in-house examples taught the model the vocabulary and the conventions that go with it, verified against the evaluation set.
Cost and latency at production volume
Every request, however trivial, went to the largest available model — slow for users and expensive at scale.
A router sends routine work to the small tuned model and reserves the frontier model for genuinely hard cases, cutting both spend and response time.
Changes shipped on instinct
Prompt tweaks were judged by trying a few examples by hand, so regressions reached production unnoticed and nobody could say if quality was rising or falling.
The evaluation harness scores each change on accuracy, format, latency, and cost, and blocks releases that regress against the current baseline.
07Measured, Not Guessed
Every Change Is Tested
Nothing reaches production without scoring at least as well as the version it replaces.
The Right Model for Each Job
Model choice is a routing decision made per request, not a single bet made once at the start.
Data Stays Put
Regulated workloads run on infrastructure the client controls, with access scoped and logged.
Predictable Output
Schema validation means downstream code can rely on the shape of what it receives.
08النتائج والتأثير
09الخاتِمة
The AI LLM project shows what changes when a language model is treated as an engineering problem rather than a magic box. By measuring before tuning, choosing models per request instead of once, and validating every output on the way out, VirtueNetz turned an expensive, unpredictable dependency into a component the team can reason about, budget for, and improve on purpose.
10ملخص المشروع
| اسـم المشـروع | AI LLM Solution |
| الدور | Model Engineering (Fine-Tuning, Evaluation & Deployment) |
| الصناعات | Applied AI / Model Engineering |
| الجمهور | Product, engineering & compliance teams |
| الغرض | Adapt, evaluate and privately deploy a language model for domain-specific production use |
| تكنولوجيا | Python, PyTorch, Hugging Face, LoRA fine-tuning, vLLM, FastAPI, Docker, Kubernetes |
| الموقع | الولايات المتحدة |
11التقنيات المستخدمة
Is your model costing more than it's earning?
VirtueNetz tunes, evaluates, and deploys language models so quality is provable, spend is predictable, and your data stays yours. virtuenetz.com · Live to Amaze
بدء مشروع

لنتحدث عن
مشروعك البرمجي أو مشروع الذكاء الاصطناعي
أخبرنا بما تبنيه، وسيراجعه مهندس خبير، لا موظف يقرأ من نص جاهز.